Most EU AI Act timelines published this year end the 2026 row at 2 August and move on to December 2027. There is another date in between, and for a large number of organisations it is the one that matters. On 2 December 2026, the transition period for marking AI-generated content closes, and two new prohibitions switch on.
The transition is narrow and easy to misread. Article 50 of the Act has applied since 2 August 2026. One duty inside it, the requirement that synthetic output carry a machine-readable mark, came with extra time for generative systems that were already on the market on that date. The European Commission's own guidance is specific: providers of those systems must comply "only as from 2 December 2026". Anything launched since August had to mark from day one.
So if you shipped a generative feature in 2024 or 2025 and concluded in August that you had a few months, those months are nearly gone. This guide covers what Article 50 actually asks for, what marking means once you try to build it, why the standard most teams reach for is weaker than it looks, what the guidance puts out of scope, and how the EU duty lines up against China and California. For the full calendar of every other Act deadline, our EU AI Act timeline is the reference and this guide does not repeat it.
The date that is missing from most timelines
Two separate things happen on 2 December 2026, and they are often reported as one.
The marking transition ends. Article 50(2) requires providers of systems that generate synthetic audio, image, video or text to ensure the output is marked in a machine-readable format and detectable as artificially generated. The Commission's transparency FAQ says the extra time applies only to systems placed on the market before 2 August 2026, and only to that one duty. Every other part of Article 50 has been live since August.
Two prohibitions begin. Regulation (EU) 2026/1744, the Digital Omnibus on AI that deferred the high-risk regime, also added two entries to the list of prohibited practices in Article 5. They cover AI systems intended to generate child sexual abuse material, and systems that generate or manipulate non-consensual intimate imagery of an identifiable person. Both apply from 2 December 2026. For providers the ban bites where that output is the intended purpose, or where it is a foreseeable and reproducible outcome and no reasonable technical safeguard was put in place. Accidental generation is expressly excluded.
The penalty tiers are worth separating because they are three times apart. Breaching a transparency obligation sits in the Article 99(4) tier, with a ceiling of 15 million euro or 3% of total worldwide annual turnover, whichever is higher, and the Article 99 text names Article 50 directly. For SMEs including start-ups, the lower of the two limbs applies instead. Prohibited practices sit in the top tier at 35 million euro or 7%. Member States set the actual regimes within those ceilings.
Four duties, and which ones are yours
Article 50 is routinely described as "the chatbot disclosure rule", which covers about a quarter of it. It contains four distinct obligations, split between providers and deployers, and most organisations carry more than one without having noticed.
| Provision | Who it binds | What it requires | When |
|---|---|---|---|
| Article 50(1) | Provider | Systems intended to interact directly with people must be designed so the person is informed they are dealing with an AI system, unless that is obvious to a reasonably well informed and observant person. | Applies |
| Article 50(2) | Provider | Synthetic audio, image, video or text output must be marked in a machine-readable format and detectable as artificially generated or manipulated. Includes general-purpose systems. | Applies; 2 Dec 2026 for systems on the market before 2 Aug 2026 |
| Article 50(3) | Deployer | People exposed to an emotion recognition or biometric categorisation system must be told it is operating, whether it runs live or after the fact. | Applies |
| Article 50(4) | Deployer | Deepfake image, audio or video must be disclosed as artificially generated. Text published to inform the public on matters of public interest must be labelled, unless it went through human review or editorial control with someone accountable for it. | Applies |
| Article 50(5) | Both | Disclosure must be clear and distinguishable, given at the latest at the time of first interaction or exposure, and meet accessibility requirements. | Applies |
Three readings catch teams out.
The deployer duties are not optional extras. A company that buys a generative tool and publishes its output is a deployer. If that output is a realistic image, audio or video of a real person, Article 50(4) applies to the publisher, not to the model provider. Marketing, communications and investor relations teams fall in scope without any model being built in-house.
A machine-readable mark does not satisfy the deepfake duty. The Commission FAQ is direct about this. Article 50(2) is a technical mark aimed at machines. Article 50(4) is a disclosure aimed at a person, to be made "upon first exposure at the latest" in a clear and visible or audible way. Embedding provenance metadata and calling the job done leaves the deployer duty open.
The "obvious" exception is narrower than it sounds. The FAQ says it is to be read restrictively. A voice agent that answers the phone sounding like a person is not covered by it just because a sophisticated listener might guess.
The editorial carve-out has a condition attached. AI-generated text on matters of public interest escapes labelling where it underwent human review or editorial control and a natural or legal person holds editorial responsibility. The Commission's position is that running a spell check does not qualify. If your newsroom, blog or research function wants to rely on this, the reviewable artefact is a record of who reviewed what, not a policy saying that review happens.
What machine-readable marking turns out to mean
The Act asks for solutions that are "effective, interoperable, robust and reliable as far as this is technically feasible". It does not name a technology, and neither do the final guidelines the Commission published in July 2026. What the guidelines do say is more useful than a mandate would have been: no single marking technique has been identified as sufficient on its own for audio, image and video. A layered approach is what is expected, for example embedded provenance metadata together with a watermark. A single technique is treated as enough for free-form text and for closed physical products.
That lands most teams on the same starting point, which is the C2PA specification and its Content Credentials. It is worth being precise about what that gives you and what it does not, because the two get conflated constantly.
The C2PA's own deployment guidance, published in July 2026, describes a credential as "a tamper-evident packet that travels with a file", digitally signed so that tools can detect whether it changed after it was attached. It then states the distinction plainly: "Though often conflated, the C2PA technical specification is distinct from watermarking and fingerprinting." Combine them and you get what the guidance calls Durable Content Credentials. Provenance metadata records what happened. A watermark survives the file being re-encoded. A fingerprint lets a lost credential be looked up again. They solve different failures.
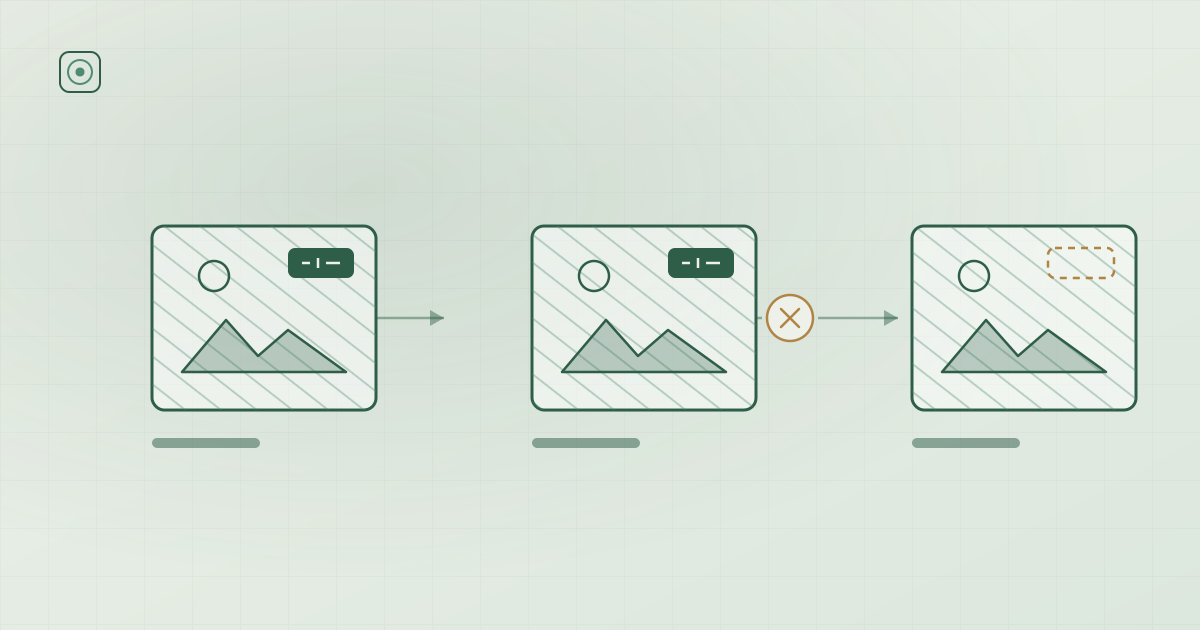
The failure that drives the layering requirement is mundane. The same guidance warns against re-exporting a file "through tools that remove metadata, as this can strip the" credential, and advises always working from the original export. A screenshot removes it. A social platform that re-encodes on upload removes it. A copy-paste into a document removes it. Metadata-only marking satisfies a conformance test and then disappears on first contact with the way content actually moves.
For text the picture is different again, and quieter than vendors suggest. Text has nowhere to hide a signature, statistical watermarks degrade under paraphrase, and the guidelines accept a single technique for free-form text for exactly that reason. Teams expecting the text case to be solved by the same control as the image case will find it is not.
Why a valid signature is not yet evidence
On 2 October 2026 the security researcher David Buchanan published a result worth understanding before anyone presents provenance to a board as proof of anything. C2PA manifests can declare exclusion ranges, byte regions left out of the signature calculation, which the format needs for legitimate reasons such as PNG checksums that change when the credential is attached.
His demonstration abuses that feature: "We can exclude the entire file, to produce an entirely valid signature over an empty string." He photographed a lottery ticket, signed it with the whole file excluded, waited for the draw, then edited the image to show the winning numbers. The credential still validated, and the trusted timestamp still asserted that the photograph predated the draw. He proposes not removing exclusions, which formats genuinely need, but specifying per format which ranges may be excluded and requiring verifiers to enforce those limits.
The governance reading of this is not that provenance is useless. It is that validating a signature and knowing what the signature covers are two different questions, and most tooling answers the first. If you are building marking to meet Article 50(2) and also planning to rely on provenance as evidence in disputes, incident investigations or takedown decisions, those are separate claims with separate assurance needs. Satisfying a regulator that output is detectable as AI-generated is a lower bar than proving an image is what it claims to be.
A practical split. Treat marking as a compliance control with a deadline, and treat provenance verification as a security capability with its own threat model. Conflating them produces a project that misses the December date while arguing about trust lists.
What the guidance puts out of scope
The least-reported part of the Commission FAQ is the list of what Article 50(2) marking does not reach. For engineering teams scoping the work, this is where the estimate shrinks.
- Short strings of numbers, symbols or letters.
- Source code.
- Machine-to-machine output that is never shown to a person.
- Closed-loop industrial or product development output, unless it is the final output.
- Standard assistive editing, and systems that do not substantially alter the input.
The final guidelines extended that last point: AI-generated translations count as standard editing and need no mark, while summaries and substantive rewrites still do. There is also a limit on the deepfake duty for evidently artistic, creative, satirical or fictional work, where disclosure can be given in a form that does not hamper the display or enjoyment of the work.
Two things follow. A code assistant generating source code is outside the marking duty, which removes a large and noisy category from scope. And the line between editing and generation is now a classification decision someone has to own and document, because translation and summarisation sit on opposite sides of it while feeling like the same feature to a user.
Three regimes, one piece of content
The EU is not the only jurisdiction asking for a label, and the three major regimes do not ask for the same thing. A single generated image distributed globally can be in scope of all three at once.
| Regime | Status | What it asks for | Dates that matter |
|---|---|---|---|
| EU AI Act Article 50 | Applies | Machine-readable marking by providers; visible disclosure of deepfakes and public-interest text by deployers; interaction disclosure | 2 Aug 2026; 2 Dec 2026 for the marking transition |
| China, Measures for Labelling AI-Generated Synthetic Content and GB 45438-2025 | In force | Both an explicit label perceptible to the user, prescribed per medium, and an implicit label in file metadata. Distribution platforms must check metadata and flag content that is or appears to be AI-generated | Issued 14 Mar 2025, effective 1 Sep 2025 |
| California AI Transparency Act, as amended by AB 853 | Phased | Covered providers: a free detection tool, an optional visible disclosure, and latent disclosures in image, video and audio. Platforms: detect provenance data, display it, do not strip it | Providers 2 Aug 2026; large online and hosting platforms 1 Jan 2027; capture devices 1 Jan 2028 |
The structural difference is where the obligation sits. The EU puts the machine-readable duty on the provider and the human-visible duty on the deployer. China requires both kinds of label and then puts a verification duty on the platform that distributes the content. California is building toward the same platform duty from January 2027, including an explicit requirement not to strip provenance data.
For anyone operating in more than one of these, the design implication is that the strictest combination wins: mark in metadata, mark perceptibly, and do not remove what arrives already marked. A pipeline built to the EU duty alone will fail the Chinese explicit-label requirement, and a platform built to pass content through untouched will fail California's non-stripping rule from 2027 if it re-encodes on upload. Our regulation tracker carries the current status of each of these instruments.
What to do before 2 December
Five weeks is enough for scoping and evidence, and not enough to design a marking scheme from scratch. Sequence accordingly.
-
Separate systems by market date, not by productThe transition applies to generative systems placed on the market before 2 August 2026. That is a per-system question, and in most portfolios the answer splits a product line rather than following it. A feature added in September to a product launched in 2024 needs its own answer. Write the list down with a date and a basis for each entry, because this is the first thing an authority will ask about.
-
Work out which of the four duties you hold, for each systemProvider duties and deployer duties land on different teams with different budgets. Most organisations are a deployer far more often than a provider, and the deployer duties have no transition at all. If you publish synthetic media or public-interest text, that obligation has been live since August.
-
Test what survives your own distribution pathGenerate a marked asset, then push it through the route your content actually takes: the CMS, the social scheduler, the email build, the partner feed. Check at each hop whether the credential is still there. This is a half-day test that tells you whether you need a watermark layer or just a metadata layer, and it produces the record that shows why.
-
Decide on the Code of Practice deliberatelyThe Commission published the final Code of Practice on marking and labelling on 10 June 2026 and the Commission and the AI Board assessed it as adequate. It is voluntary, and the Commission states plainly that not signing it does not constitute non-compliance. Non-signatories simply have to demonstrate compliance by other adequate means. Either answer is defensible. Not having made the decision is not, because the alternative evidence takes longer to assemble than the signature does.
-
Fix the interaction disclosure while you are in thereArticle 50(1) is the cheapest of the four to close and the easiest to fail on a technicality. Check that every conversational surface declares itself at the start of the first interaction, including voice channels, embedded widgets and anything a partner white-labels from you. The accessibility requirement in 50(5) applies here too.
-
Record the scope decisions, including the exclusionsDeciding that a system is out of scope because it produces source code, or machine-to-machine output, or translations rather than summaries, is a compliance decision. It needs a written basis and an owner, exactly like an in-scope control does. Undocumented exclusions are the gap that turns a defensible position into an unanswerable question.
The trade-offs nobody puts on the slide
Marking is a product decision as well as a compliance one. Visible disclosure changes how content performs, and the teams who will carry it are usually not the teams who read the regulation. Bringing marketing and communications into the scoping rather than the rollout avoids a late argument about where the label goes.
The technical standard is still moving. The provenance specification has had multiple releases, a public weakness was disclosed in October 2026, and the Commission has deliberately not frozen a technique. Building a marking pipeline that assumes one fixed format will need revisiting. Building one that treats the marking layer as replaceable will not.
Detection tooling will be asked for before it is good. Once content carries marks, somebody will ask you to detect unmarked content as well, usually after an incident. Detection of AI-generated media without a cooperating marker is an unsolved problem, and a governance programme that implies otherwise is storing up a credibility failure.
Two Commission pages disagree on a detail. The transparency FAQ and the signing FAQ give slightly different lists of which Article 50 paragraphs the Code of Practice supports. It makes no practical difference to whether you sign, but it is a reminder that official guidance in this area is young. Cite the provision, not somebody's summary of it, when the position has to hold up.
Frequently asked questions
Where this leaves you
Transparency obligations get treated as the easy tier of the AI Act, below the conformity assessments and technical documentation that high-risk systems carry. The duties are lighter. The engineering is not. Marking asks for something to survive a content pipeline that was designed to strip exactly that kind of metadata, using a standard that is still changing and had a public weakness disclosed this October.
What makes 2 December manageable is that the hard part is scoping rather than building. Which systems were on the market in August. Which of the four duties each one carries. What survives your own distribution path. Which outputs are excluded and on what basis. Those four answers are the compliance position, and three of them are research rather than engineering. The organisations that will struggle in December are not the ones with an imperfect watermark. They are the ones that cannot say which systems the question applies to.
Where a governance platform fits. Knowing which generative systems you placed on the market, when, and which transparency duty each one carries is an inventory problem before it is a marking problem, and the evidence has to survive being asked for a year later. Holding that register with owners, dates, scope decisions and the obligation each system maps to is governance work, and it is what a platform such as Holistic AI is built to carry. The marking itself stays an engineering job in the product.